Three Parts and No Brain
What a chess program is made of, and how far a hand-written one gets against the computer opponent on lichess, before any learning starts.
| Duration | 16 minute read |
|---|---|
| Published | |
| Series | Learning To Play |
| Topics | Game AI, Tree search, Games, Rust, Metrics, Probability, Chess, Shogi, Go |
In short
Before any learning starts, I built Kishi’s chess engine from the three parts Levy described: the board as numbers, an evaluation that says who is better, and a search that looks ahead. The bitboard representation is checked by perft on every change, and the hand-written PeSTO evaluation holds almost none of the chess; the strength lives in the search and its pile of tuned statistical bets. Measuring strength honestly is the hardest part: matches need paired openings, equal search budgets and stated margins of error, and a small positive result without proof means keep it and do not claim it. Against a rebuilt version of the lichess computer, Kishi with its hand-written evaluation on one core sits between level 6 and level 7, with wide margins that I report rather than leave off. The same construction gives a fair club opponent in shogi, while Go needs random playouts instead, and this baseline is the opponent every trained neural network in the project will have to beat.
The chess computer on lichess has eight levels. I play it on trains, on my phone, and like everyone who plays it I have a level I can beat and a level that beats me. When I built my own engine last month, the first question from anyone I showed it to was the same question I had been asking myself: what level is it? It sounds like the easiest thing in the world to answer. It turned out to be the hardest part of the whole project, harder than getting the program to play at all, and the answer is the point of this piece.
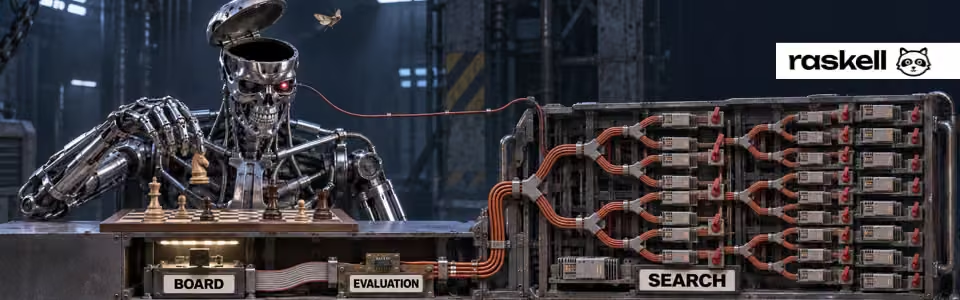
In the first piece I told the story of Demis Hassabis at twelve, reading David Levy’s handbook on chess computers and learning that a chess program is three parts: the board turned into numbers, a function that says who is better, and a search that looks ahead. I built the three parts in Rust, and I want to show what each one turns out to be once you build it, because the surprise is which of them holds the chess. Then I want to put a number on the result, and show why the number comes with a margin of error that most people quietly leave off.
Nothing in this piece learns. That is deliberate. A neural network that learns to evaluate chess positions needs something to play the games it learns from, and something to beat afterwards, or there is no way to tell whether it learned anything. This is that something.
The board, as numbers
Levy’s first part is the one that sounds trivial and is not. A chessboard has 64 squares and a modern processor works with 64-bit numbers, so the natural representation is one number per kind of piece, with a bit set for every square that kind of piece stands on. Twelve numbers, one for each of white’s and black’s six piece types, and you have the position. A move is sixteen bits: where from, where to, and a few bits for what kind of move it is. The whole state of a game fits in less memory than this paragraph.
The reason to care is speed. Asking “where can this knight go” becomes a lookup in a table; asking “is the king attacked” becomes a handful of ANDs and ORs on those numbers. An engine asks those questions tens of millions of times a second, and every one of them has to be exactly right, because the rules of chess have corners. Castling through check. The pawn that captures en passant and, in doing so, uncovers a check on its own king along the rank. A program with one rare bug in its move generation plays a thousand games without incident and then loses one by making an illegal move, and nobody notices which rule it was.
The test for this has a name, perft, and it is the first thing any engine author runs. You count every legal sequence of moves to a fixed depth from a known position and compare with the published numbers, which have been agreed on for decades.
| Moves ahead | Positions reachable from the start |
|---|---|
| 1 | 20 |
| 2 | 400 |
| 3 | 8,902 |
| 4 | 197,281 |
| 5 | 4,865,609 |
If your program says 4,865,609 at depth five, your rules are right, at least for the starting position. There is a second position everyone uses, nicknamed Kiwipete, with castling rights and en passant and promotions all live at once, and a handful of nastier endgames. Kishi runs the whole suite on every change. Every match tool in the project also checks the opponent’s moves against Kishi’s own generator, so if the two programs ever disagree about the rules, the game fails loudly instead of being quietly scored.
One decision follows the engine everywhere afterwards. A position in Kishi is a small value that is copied, not modified. Making a move hands you a new position and leaves the old one untouched, so there is no “unmake” and no way for the two to drift apart. It costs a copy of a couple of hundred bytes per move and buys code that cannot get out of sync with itself. For a program that would later be compiled to WebAssembly and run on several threads at once, that was the right trade, and I would make it again.
The evaluation
Levy’s second part is the one I expected to hold the chess, and it holds almost none. The evaluation looks at a single position, without looking ahead, and returns a number: who is better and by how much, in hundredths of a pawn. Plus 100 means the side to move is a pawn up, or has the equivalent in position. Levy’s example, in the book Hassabis read, was material against mobility: if the pieces you have left matter twice as much as the squares they can reach, double the material score before adding the mobility score. The idea is still exactly that, weights on things you can count.
Kishi’s hand-written evaluation is a well-known set of tables called PeSTO. For each of the twelve kinds of piece there is a table of 64 numbers, one per square: a knight in the centre is worth more than a knight on the rim, a king belongs in the corner in the middlegame and in the centre in the endgame, a pawn far up the board is worth more than one at home. There are two tables per piece, one for the middlegame and one for the endgame, and the evaluation blends them by how much material is left. Add up the entries for the pieces on the board, and that is the number.
It knows nothing else. Nothing about pawn structure beyond where each pawn stands, nothing about king safety beyond where the king stands, nothing about whether a rook is on an open file, nothing about how any two pieces relate to each other. It is 768 numbers twice, and an interpolation, and it plays chess well enough to beat most people who play chess, which tells you something about where the strength of these programs lives. It is not in the knowledge.
I will come back to the number 768 in the next piece, because the neural network that is supposed to replace this table has exactly 768 inputs, and the coincidence is not one.
There is one small piece of learning in the engine already, and it is worth a sentence as the smallest possible example of the idea this whole project is about. The search keeps a table of how wrong the evaluation has recently been for each pawn structure it has seen, and corrects the evaluation by that running average before using it. The correction is learned during the game, from the search’s own deeper results, and thrown away afterwards.
The search
Levy’s third part is where the engineering is, and where the strength comes from. The search tries every move, and every reply, and every reply to those, building a tree of positions that might be reached, and asks the evaluation about the positions at the tips. The textbook version is minimax: assume your opponent always picks the reply that is worst for you, and choose the move whose worst case is best. Alpha-beta is minimax with a proof that most of the tree does not matter. Once a reply has shown that a move is bad enough, you stop reading the rest of that move’s continuations, the way you stop reading a contract clause once you have found the sentence that kills the deal. With the best move examined first at every step, alpha-beta sees as far as minimax while visiting roughly the square root of the positions.
Everything a modern engine does on top of that is a bet about chess, and every bet is sometimes wrong. The engine is tuned so that the extra depth the bets buy is worth more than the mistakes they cost.
| The technique | The bet | In Kishi |
|---|---|---|
| Transposition table | the same position is reached by different move orders, so remember what you found | 16-byte entries in a table all threads share without locks |
| Move ordering | look at the likely best move first, so the cut-offs come early | the move the table remembers, then captures by value, then moves that cut off recently |
| Null-move pruning | if doing nothing is already good enough, moving is too; skip the rest | a shallower search after a pass, shallower still the further ahead you are |
| Reverse futility | far above the target at shallow depth, stop looking | the margin is 75 hundredths of a pawn per move of depth, up to eight |
| Late move reductions | moves that order late are rarely best, so search them shallower | a formula in the logarithm of depth and move number |
| Singular extensions | one move much better than every alternative deserves a deeper look | from eight moves of depth |
| Quiescence | never evaluate in the middle of an exchange | keep capturing until the position is quiet, then ask |
None of these are mine. They are the shared inheritance of open-source engines, worked out over thirty years by people who tested each one with tens of thousands of games, and they are why Kishi’s search is a few thousand lines rather than a research project. What I want you to take from the table is its shape. A chess search is a pile of statistical bets, each with a margin written in hundredths of a pawn, each tuned against the particular evaluation it runs with. The bets do not know what the evaluation is. In the next piece the evaluation changes, and that sentence becomes expensive.
With all of it in place, on one core of the laptop, the engine examines about three million positions a second and looks seventeen to twenty half-moves ahead in half a second, the time it takes to tap the board. Deep Blue, in 1997, looked twelve to sixteen half-moves ahead by examining two hundred million positions a second on hardware built for nothing else. Sixty times fewer positions, and a little further: the difference is the bets.
How you know anything
Now the hard part. Two chess programs can play each other, and one wins more often, and you would like to turn that into a number. Chess has had such a number since the 1960s: the Elo rating, the number every club player knows, and the one I first met at regional tournaments as a teenager, which is why the arithmetic has never felt abstract to me. A difference of 400 points means ten-to-one odds. A difference of 100 points means the stronger side scores about 64 percent. The rating difference between two programs is computed from the score of a match between them, and the catch is that the score of a short match is mostly noise.
Chess engine developers have one honest instrument for this, and it is worth describing because the design is where the honesty lives. The two programs play a few hundred games from the same random openings, each opening played twice with the colours swapped, so that a lucky opening cannot favour one side. Both sides get the same number of positions to search per move, so that a faster program cannot pass for a stronger one. And the result comes with a margin of error, at 95 percent confidence, that depends on how many games were played.
| Games | Margin of error |
|---|---|
| 20 | about 200 rating points either way |
| 400 | about 32 |
| 600 | about 23 |
Before I trusted the instrument I pointed it at itself. The same program on both sides, ten thousand positions a move, six hundred games:
Kishi vs Kishi, 10,000 nodes a move, 600 games: +211 =181 -208 elo +1.7 ± 23.3Plus 1.7 with a margin of 23 is the instrument reading zero, which is what it should read when nothing has changed. Then the real test, the pawn-structure correction described above against the engine without it:
Kishi vs Kishi without correction, 600 games: +219 =180 -201 elo +10.4 ± 23.3That is probably positive and not proven. The big engine projects run this test with tens of thousands of games per change and a statistical rule that stops the match as soon as the answer is clear either way. On a laptop, six hundred games is an evening, and the honest reading of plus ten with a margin of twenty-three is “keep it, and do not claim it”. I have found that sentence useful well outside chess.
The lichess ladder
A match between two versions of Kishi says which is better. It says nothing about how good either of them is. For that, the program has to play something whose strength people already know, and the most useful yardstick I know is the one in your pocket: lichess’s computer opponent, because everyone has played it and everyone has a level that beats them.
The eight levels are not eight different programs. They are Stockfish, the strongest open-source engine in the world, deliberately weakened in three ways at once: a skill setting that makes it pick worse moves on purpose, a cap on how many moves ahead it may look, and a time limit per move. The settings are public, in the client lichess runs, so the opponent can be rebuilt exactly on a laptop.
| Level | Skill | Depth | Time per move |
|---|---|---|---|
| 1 | −9 | 5 | 50 ms |
| 2 | −5 | 5 | 100 ms |
| 3 | −1 | 5 | 150 ms |
| 4 | 3 | 5 | 200 ms |
| 5 | 7 | 5 | 300 ms |
| 6 | 11 | 8 | 400 ms |
| 7 | 16 | 13 | 500 ms |
| 8 | 20 | 22 | 1,000 ms |
Stockfish’s own skill setting stops at zero, so levels 1 to 3 as I rebuild them are a little stronger than the real ones. Levels 4 to 8 are exact. Kishi played Stockfish 19 on one core, twenty games a level, with the time its own app gives the matching level:
| Opponent | Kishi’s time per move | Score | Rating difference |
|---|---|---|---|
| lichess level 4 | 200 ms | 19 of 20 | +511, give or take 646 |
| lichess level 6 | 500 ms | 13 of 20 | +108, give or take 165 |
| lichess level 7 | 500 ms | ½ of 20 | −636, give or take 579 |
Twenty games a level gives margins you could drive a bus through, which is why they are in the table rather than left off. What the numbers do allow you to say is this: with the hand-written evaluation, on one core, at half a second a move, Kishi sits between lichess’s level 6 and level 7. If level 6 is the one that beats you, Kishi beats it two games in three. Level 7 is Stockfish thinking thirteen moves deep with most of its strength intact, and one draw in twenty games is an honest description of the distance. Level 8 is Stockfish at depth 22, which is to say Stockfish, and no evaluation function written by hand on a laptop is going to get there.
The app plays on four cores on a phone, and these numbers come from one, so the opponent you meet at kishi.raskell.io is a little stronger than the table. I will measure it again with the phone’s budget as the trained neural networks arrive, because that is the measurement that will decide whether they ship.
The same three parts, twice more
Shogi got the same construction: the board as numbers, with the extra wrinkle that captured pieces sit in a hand and can come back; a hand-written evaluation that counts material, with pieces in hand worth a little more than pieces on the board, and rewards golds and silvers near your own king; and the same search with the same bets. Against Fairy-Stockfish, the variant engine that plays shogi, at half a second a move, it wins twenty games out of twenty at the weakest skill setting and two out of twenty at a middling one. A fair club opponent, nowhere near strong play, and the hand-written evaluation is already where the design strains: with pieces returning to the board, there is no endgame to simplify into, and a table of squares says less and less.
Go did not get the three parts, because they do not work. There is no table of 361 squares that tells you who is winning a Go position, and a search that looks four moves ahead on a nineteen-by-nineteen board sees almost nothing. The Go engine in Kishi plays the way the programs of 2008 played, by playing thousands of fast random games to the end and counting, and against GNU Go at its lowest level it wins three games in ten. That method, and why it was the dead end AlphaGo had to get out of, is a piece of its own.
What it cost
| The engine | a few days of Rust, written with a coding agent, me steering |
| The rules test | seconds, on every change |
| Positions searched per second, one core | 3 to 3.7 million |
| A 600-game match at 10,000 positions a move | an evening on ten cores |
| Twenty games against a lichess level | minutes |
The baseline is the most important number in this whole project, and the least glamorous. It is the opponent every trained neural network has to beat, the player that will generate the first games they learn from, and the thing the rest of the work is trying to make unnecessary. Levy’s three parts, built, hold a hand-written table of 768 numbers and a great deal of search, and they land between level 6 and 7 of the computer on your phone. The next piece gives the table a hidden layer and finds out what that costs.
References
- Ronald Friederich, PeSTO’s evaluation function, Chess Programming Wiki.
- Perft results, Chess Programming Wiki.
- lichess, fishnet, the client that plays the computer levels, with the level table.
- Arpad Elo, The Rating of Chessplayers, Past and Present (Arco, 1978).
- Kishi:
engine/for the search and evaluation,tools/for the match runners,docs/study/notebook.mdfor every match quoted here.